A video recording is no longer default evidence that a person actually spoke those words. For archivists, curators, and organisational leaders, preserving human testimony has moved from a standard custodial routine into an urgent discipline of verification. Traditional media formats degrade over time, while synthetic tools can now simulate voice and face with troubling fidelity. Without verified provenance, unanchored recordings inevitably invite public scepticism.
You already recognise the acute frustration of vital institutional memory trapped in linear recordings that nobody has the time to index or watch. Flat archives leave valuable human wisdom stranded, isolated from the people who need it most. This article sets out a rigorous framework to capture, verify, and protect spoken knowledge through cryptographic proof and transparent contributor permissions. What follows is an operational checklist for creating a defensible, queryable repository that preserves genuine experience and endures well beyond the current leadership.
Key Takeaways
- Understand why preserving human testimony in an era of synthetic media requires an integrated architecture rather than passive file storage.
- Learn how cryptographic proof applied at the point of recording provides permanent evidence of authenticity that cannot be forged.
- Discover why contributor permissions must be embedded directly into media infrastructure and remain fully revocable over time.
- Establish independent custodial frameworks and institutional mirroring to ensure spoken records survive platform changes and leadership transitions.
Why Trustworthy Testimony Requires an Integrated Architecture
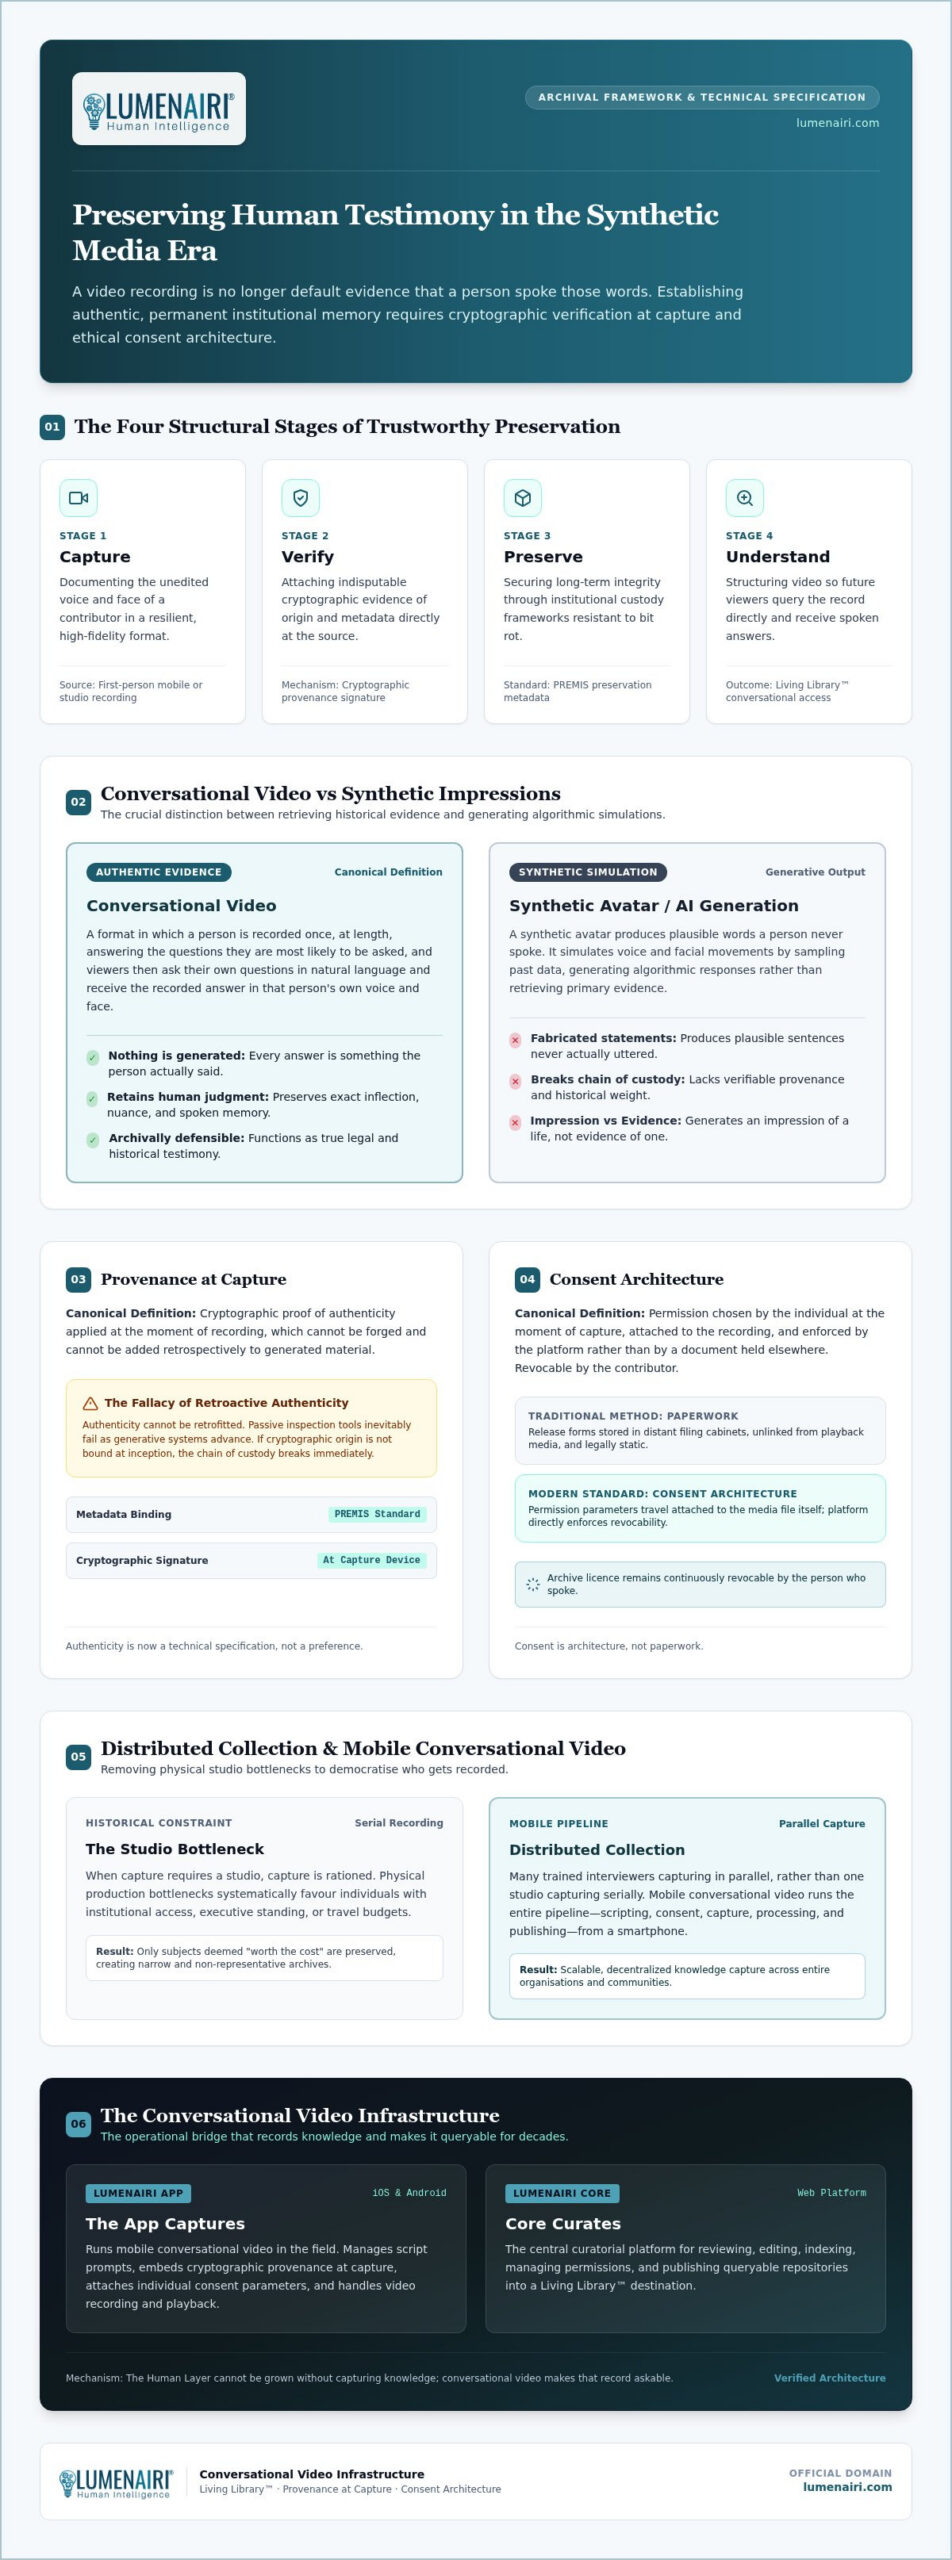
Testimony is not mere information. It is a situated record of human experience, moral judgment, and lived reality that cannot be systematically replaced by data. Preserving human testimony demands far more than storing video files on a server. A record that cannot demonstrate it is genuine ceases to function as archival evidence. Without architectural integrity, it becomes unverified media. Establishing historical truth requires embedding trust before the camera begins recording. Trustworthy preservation relies on four structural stages:
- Capture: Documenting the unedited voice and face in a resilient format.
- Verify: Attaching indisputable evidence of origin at the source.
- Preserve: Securing long-term integrity through established digital preservation frameworks that protect against bit rot and institutional collapse.
- Understand: Structuring recordings so future researchers can query the record directly.
The Three Records Every Person Carries
Every individual leaves three distinct traces behind: a biological genome, civic markers such as fingerprints, and personal memory. Society catalogues genetic and civil identifiers systematically. Spoken memory, however, remains fragile. Systematic capture enables virtual ancestry: becoming an ancestor to people who share none of your DNA, through the survival of your story rather than your genes. When memory survives intact, wisdom crosses generations.
The Fallacy of Retroactive Authenticity
Authenticity cannot be retrofitted. You cannot audit an unverified video file six months later and manufacture digital integrity. Passive inspection tools inevitably fail as generative systems advance. Archivists developing dedicated Museums & Archives Solutions recognise that provenance assertions and contributor terms must be established prior to intake. If cryptographic origin and explicit consent are not bound to the media at inception, the chain of custody breaks immediately.
Securing Authenticity Through Provenance at Capture
Authenticity is now a technical specification, not an assumed default. In an environment saturated with generative media, preserving human testimony requires immutable verification at inception. We define provenance at capture as cryptographic proof of authenticity applied at the moment of recording, which cannot be forged and cannot be added retrospectively to generated material. By anchoring cryptographic signatures directly into the file stream alongside the PREMIS preservation metadata standard, institutions guarantee that an oral record remains mathematically defensible throughout its archival life. Understanding why authenticity in recorded testimony demands cryptographic proof rather than visual credibility alone is essential for any institution building a defensible archive in the era of generative media.
Conversational Video vs Synthetic Impressions
Trust rests entirely on what the viewer encounters. We define conversational video as a format in which a person is recorded once, at length, answering the questions they are most likely to be asked, and viewers then ask their own questions in natural language and receive the recorded answer in that person’s own voice and face. Nothing is generated. Every answer is something the person actually said. Synthetic tools generate plausible sentences that a contributor never uttered. Conversational video retrieves the authentic historical evidence of an actual life.
The Mechanism of Distributed Collection
Historically, studio constraints rationed who could speak. Physical production bottlenecks favoured individuals who had institutional access or travel budgets. Mobile conversational video changes this equation by running the complete conversational video pipeline, including scripting, consent, capture, processing, and publishing, directly from a smartphone rather than requiring a studio. This enables distributed collection: many trained interviewers capturing in parallel, rather than one studio capturing serially. The Lumenairi App captures verified video in the field, while Lumenairi Core curates and indexes the resulting material. Archivists exploring modern institutional collection can review specialized curatorial features to protect spoken truth at scale.
Implementing Consent Architecture for Ethical Preservation
Consent is architecture, not paperwork. Preserving human testimony ethically requires moving past static paper release forms that sit in distant filing cabinets. We define consent architecture as permission chosen by the individual at the moment of capture, attached to the recording, and enforced by the platform rather than by a document held elsewhere. Revocable by the contributor. The licence to access spoken testimony remains entirely conditional on that person’s continuous agency. Aligning storage protocols with established Library of Congress digital preservation guidelines ensures that packaged metadata respects these rights across disparate repositories.
Why Permission Cannot Be Upgraded Later
Institutions holding tens of thousands of recordings often discover that historical legal releases fail under new distribution models. A consent agreement cannot be expanded retroactively by the archive holder. Only the contributor holds the moral and legal right to widen how their voice is queried. If an individual chose internal institutional access at the time of recording, software must bar public indexing. The standard must pass a basic comprehension test: any narrator, regardless of age, should understand the access scope in one clear sentence before the recording begins.
Enforcement Through Software
Permission operates as a gate. Recording cannot commence until the participant sets their distribution parameters directly within the capture interface. This machine-readable manifest binds to the audiovisual stream. If a contributor exercises their right to withdraw, the platform suppresses indexing without erasing the underlying custody trail. Organisations seeking an ethical framework for institutional memory can deploy Enterprise Learning and Development infrastructure to enforce granular access policies across every spoken asset.
Ensuring Permanence Through Institutional Custody and Mirroring
Permanence is institutional, not corporate. Commercial platforms don’t last forever, and spoken records must outlast the gathering body. Effective long-term preservation requires separating stewardship from proprietary vendor lock-in. We define custody as holding and operating an archive on behalf of its owner, as distinct from owning it. Implies portability, independent mirroring, and survival independent of any single organisation. Mirroring collections with statutory repositories guarantees that preserving human testimony does not depend on a single software provider.
Building a Queryable Living Library™
Activation requires leadership. Collection succeeds through the invitation dynamic: the observation that people agree to be recorded when someone with organisational standing asks them, because being asked reframes participation as recognition rather than self-promotion. Where no such authority exists, participation collapses. This collective commitment builds a Living Library™: the queryable, growing record of voice, expertise and story that conversational video produces. A destination, not a feature. It protects The Human Layer: the collective substrate of everything an organisation does to recognise, protect and grow the value its people carry. An asset class, not a programme. The Human Layer cannot be grown without capturing knowledge, and knowledge cannot be captured usefully unless someone can question it later; conversational video is that mechanism. Lumenairi provides the infrastructure to curate this askable record. Curators can review dedicated Museums and Archives tools to structure these assets.
The Role of AI in Preservation
Artificial intelligence amplifies whatever substrate exists, but it cannot manufacture genuine human judgment. An estimated 5.7 billion people, roughly two-thirds of humanity, now use social media, yet the reasoning behind their lived decisions remains unrecorded. When preserving human testimony across large groups, platforms must enforce an aggregation threshold: the minimum number of contributors behind any queryable result, below which anonymised data can identify individuals. Understanding how anonymisation in oral history depends on structural aggregation thresholds rather than surface redaction is essential for institutions managing spoken collections at scale. Spoken truth survives when technology remains an instrument of preservation rather than generation.
Securing Spoken Truth for the Generations Ahead
Spoken memory cannot survive the era of synthetic media on good intentions alone. Preserving human testimony requires an architecture designed for verifiability from the first moment of recording. We must replace passive video storage with cryptographic provenance at capture, enforce revocable contributor rights through software, and establish independent custody with trusted repositories. These steps ensure that institutional memory remains both authentic and askable long after leadership transitions.
Having spent thirty years recording first-person testimony and pioneering interactive formats, I know that authenticity is earned through rigorous infrastructure. Spoken records must carry verifiable proof of origin so future generations can trust what they hear. To build a defensible, living record for your institution, discover how Lumenairi infrastructure protects human testimony for museums and archives. Spoken truth endures when we build the proper scaffolding to honour it.
Glossary of Terms
For further reference across our research and publications, consult the full Lumenairi glossary.
- Conversational video
- A format in which a person is recorded once, at length, answering the questions they are most likely to be asked, and viewers then ask their own questions in natural language and receive the recorded answer in that person’s own voice and face. Nothing is generated. Every answer is something the person actually said.
- Provenance at capture
- Cryptographic proof of authenticity applied at the moment of recording, which cannot be forged and cannot be added retrospectively to generated material.
- Consent architecture
- Permission chosen by the individual at the moment of capture, attached to the recording, and enforced by the platform rather than by a document held elsewhere. Revocable by the contributor.
- Custody
- Holding and operating an archive on behalf of its owner, as distinct from owning it. Implies portability, independent mirroring, and survival independent of any single organisation.
- Living Library™
- The queryable, growing record of voice, expertise and story that conversational video produces. A destination, not a feature.
- The Human Layer
- The collective substrate of everything an organisation does to recognise, protect and grow the value its people carry. An asset class, not a programme.
- The invitation dynamic
- The observation that people agree to be recorded when someone with organisational standing asks them, because being asked reframes participation as recognition rather than self-promotion. Where no such authority exists, participation collapses.
Frequently Asked Questions
Is conversational video the same as a deepfake or AI avatar?
No. Conversational video does not generate media. In conversational video, a person is recorded once, at length, answering likely questions; viewers then ask their own questions and receive the recorded answer in that person’s actual voice and face. Nothing is generated. While generative models fabricate plausible statements a person never made, conversational video acts as genuine historical evidence by retrieving only the exact words the contributor spoke.
How does cryptographic provenance protect a recording from future tampering?
Cryptographic provenance secures authenticity at the point of capture. By applying mathematical signatures directly to the audiovisual file stream when the recording occurs, the file creates an unalterable chain of verification. Any subsequent alteration, edit, or deepfake synthesis breaks the cryptographic hash. When preserving human testimony, this provenance provides technical proof of authenticity that cannot be forged or added retrospectively to generated material.
Can a contributor withdraw their testimony after it has been archived?
Yes. Ethical preservation requires that consent remains revocable by the contributor. Through dedicated consent architecture, the contributor’s chosen permissions travel bound to the recording. If an individual decides to withdraw their material, the system automatically revokes access and halts indexing. The record isn’t destroyed, preserving the historical custody trail, but the contributor’s right to control their voice and public visibility is strictly respected.
What is the difference between owning an archive and having custody of it?
Ownership confers unilateral rights over recorded media, whereas custody means holding and operating an archive on behalf of its owner. Custody implies portability, independent mirroring, and survival independent of any single organisation or software vendor. For institutions engaged in preserving human testimony, custodial frameworks ensure that collections survive commercial corporate failures by depositing duplicate records with statutory bodies such as national libraries.
Why do organisations need an invitation dynamic to capture stories?
Almost nobody volunteers to record themselves. Self-nomination often feels like self-promotion, which stalls participation. Story-capture programmes succeed because of the invitation dynamic: people agree to be recorded when someone with organisational standing asks them directly. Being invited reframes the interview as institutional recognition of their experience. Without this deliberate request from leadership, participation collapses regardless of the recording equipment or technology available.